Key facts
- Original authors
- Runway (company) , CompVis, and Stability AI
- Developer
- Stability AI
- Initial release
- August 22, 2022
- Stable release
- SD 3.5 (model) / October 22, 2024
- Written in
- Python
- Type
- Text-to-image model
- License
- Stability AI Community License
- Website
- stability .ai /stable-image
- Repository
- github .com /Stability-AI /generative-models
via Wikipedia infobox
Described at
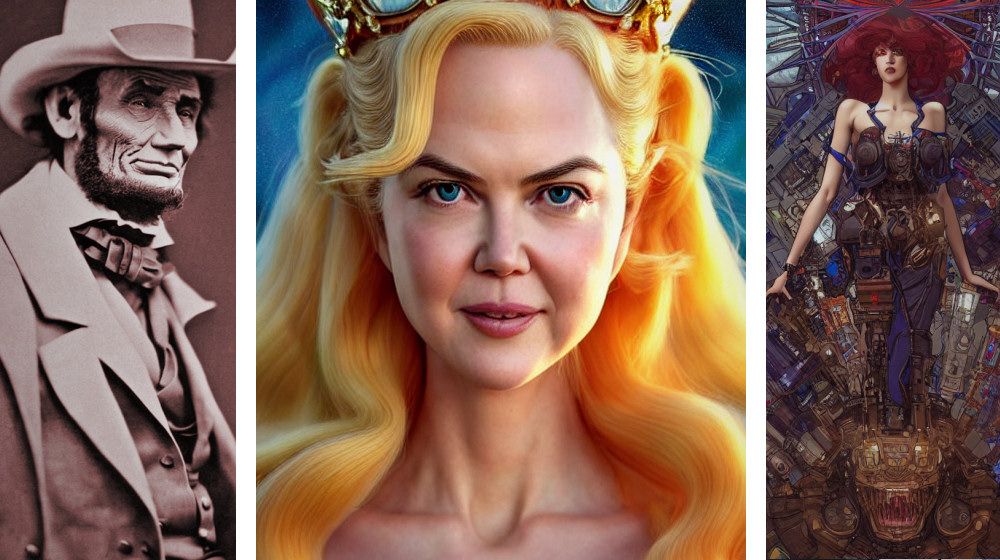
With Stable Diffusion, you may never believe what you see online again - Ars Technica
AI image synthesis goes open source, with big implications.
arstechnica.com →Link to a page describing this subject · 40,000 chars · not written by Vinony
Source code
Stable Diffusion is a latent text-to-image diffusion model. Thanks to a generous compute donation from Stability AI and support from LAION, we were able to train a Latent Diffusion Model on 512x512 images from a subset of the LAION-5B database. Similar to Google's Imagen, this model uses a frozen CLIP ViT-L/14 text encoder to condition the model on text prompts. With its 860M UNet and 123M text encoder, the model is relatively lightweight and runs on a GPU with at least 10GB VRAM. See this section below and the model card. Stable Diffusion v1 refers to a specific configuration of the model architecture that uses a downsampling-factor 8 autoencoder with an 860M UNet and CLIP ViT-L/14 text encoder for the diffusion model. The model was pretrained on 256x256 images and then finetuned on 512x512 images. Note: Stable Diffusion v1 is a general text-to-image diffusion model and therefore mirrors biases and (mis-)conceptions that are present in its training data. Details on the training procedure and data, as well as the intended use of the model can be found in the corresponding model card. The CreativeML OpenRAIL M license is an Open RAIL M license, adapted from the work that BigScience and the RAIL Initiative are jointly carrying in the area of responsible AI licensing. See also the article about the BLOOM Open RAIL license on which our license is based. Stable Diffusion is a latent diffusion model conditioned on the (non-pooled) text embeddings of a CLIP ViT-L/14 text encoder. We provide a reference script for sampling, but there also exists a diffusers integration, which we expect to see more active community development. Note: The inference config for all v1 versions is designed to be used with EMA-only checkpoints. For this reason use ema=False is set in the configuration, otherwise the code will try to switch from non-EMA to EMA weights. If you want to examine the effect of EMA vs no EMA, we provide "full" checkpoints which contain both types of weights. For these, use ema=False will load and use the non-EMA weights. By using a diffusion-denoising mechanism as first proposed by SDEdit, the model can be used for different tasks such as text-guided image-to-image translation and upscaling. Similar to the txt2img sampling script, we provide a script to perform image modification with Stable Diffusion. Here, strength is a value between 0.0 and 1.0, that controls the amount of noise that is added to the input image. Values that approach 1.0 allow for lots of variations but will also produce images that are not semantically consistent with the input. See the following example. This procedure can, for example, also be used to upscale samples from the base model. Comments Our codebase for the diffusion models builds heavily on OpenAI's ADM codebase and Thanks for open-sourcing! The implementation of the transformer encoder is from x-transformers by lucidrains.
Excerpt from the source-code README · 12,436 chars · not written by Vinony
Wikidata facts
- Named after
- diffusion model
- Official website
- stability.ai/stable-image
- Image
- Astronaut Riding a Horse (SD3.5).webp
Show 12 more facts
- inception
- 2022-08-22
- Commons category
- Stable Diffusion
- described at URL
- arstechnica.com/information-technology/2022/09/with-stable-diffusion-you-may-never-believe-what-you-see-online-again
- source code repository URL
- github.com/Stability-AI/generative-models
- uses
- deep learning
- programmed in
- Python
- software version identifier
- 3.5
- official demo URL
- huggingface.co/spaces/stabilityai/stable-diffusion
- hashtag
- StableDiffusionArt
- official jobs URL
- stability.ai/careers
- operating system
- Microsoft Windows
Sources (9)
via Wikidata · CC0
Article · 中文
Stable Diffusion是2022年發布的深度學習。它主要用於根據文本的描述產生詳細圖像,儘管它也可以應用於其他任務,如內補繪製、外補繪製,以及在指導下產生圖生圖的翻譯。 它是一種,由慕尼黑大學的CompVis研究團體開發的各種生成性人工神經網絡。它是由初創公司StabilityAI,CompVis與Runway合作開發的,並得到EleutherAI和的支持。 截至2022年10月,StabilityAI籌集了1.01億美元的資金。 Stable Diffusion的代碼和模型權重已公開發布,可以在大多數配備有適度GPU的電腦硬件上運行。而以前的專有文生圖模型(如DALL-E和)只能通過雲端運算服務訪問。
Abstract from DBpedia / Wikipedia · CC BY-SA